FlexLMV-Net
📌 Overview
FlexLMV-Net (Longitudinal Multi-View Network) is a deep learning model for breast cancer risk prediction from mammography. It jointly models multi-view imaging (CC, MLO) and longitudinal information (current and prior exams) to produce risk estimates over multiple future time horizons.
The model integrates temporal alignment, feature-Aware Temporal Fusion, cross-view feature fusion, and multi-head risk prediction within a unified framework.
🧠 Key Idea
FlexLMV-Net is built around three core ideas:
- Explicit longitudinal alignment: Previous mammography feature maps are spatially aligned with the current-examination feature maps using a registration network (MammoRegNet), enabling meaningful temporal comparisons across a variable number of prior examinations.
- Feature-aware temporal fusion: Aligned prior features and difference features are independently aggregated, allowing the model to adaptively capture historical breast appearance and temporal changes while accounting for examination-specific information and temporal distance.
- Cross-view fusion and multi-level prediction: CC and MLO views are fused using self-attention and cross-attention mechanisms, with risk predictions generated at both view-specific and fused multi-view levels.
This design enables FlexLMV-Net to capture longitudinal changes, cross-view consistency, and variable-length imaging histories, adapting to the amount of prior mammography information available for each patient.
🏗️ Architecture
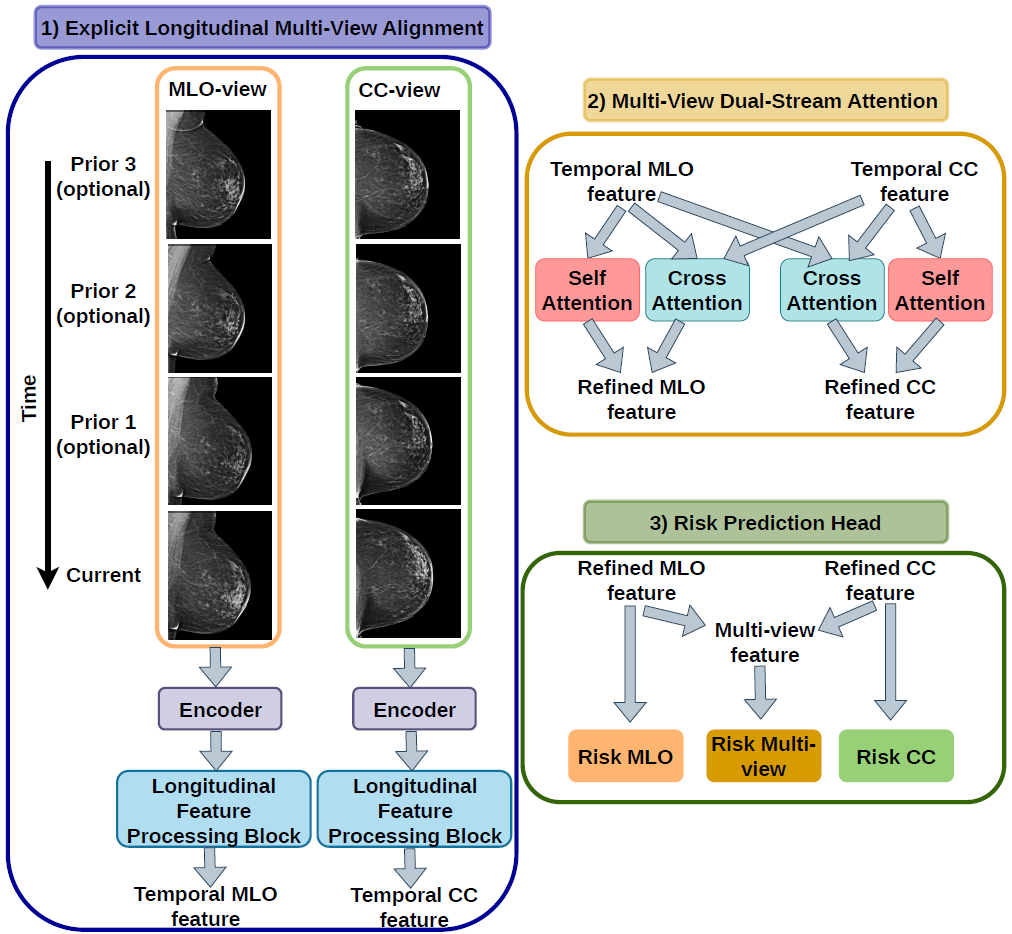
The model consists of four main components:
1. Explicit Longitudinal Multi-View Alignment
- Uses a shared encoder to extract feature maps from each mammographic view (CC and MLO) across all available examinations.
- Applies a registration network (MammoRegNet) to spatially align all prior feature maps with the corresponding current-examination feature map.
- Difference features are computed between consecutive examinations.
- Supports a variable number of aligned prior and difference feature maps, accommodating patients with different lengths of imaging history.
2. Feature-Aware Temporal Fusion
- Aggregates information from a variable number of prior examinations to accommodate different longitudinal imaging histories.
- Separately aggregates aligned prior features and difference features into compact longitudinal representations, preserving historical appearance and temporal changes.
- Learns to weight each examination according to its feature content, temporal distance from the current examination, and spatial relevance.
- Concatenates the current-examination features with the fused aligned-prior and difference representations to construct a comprehensive longitudinal feature representation for each view.
3. Multi-View Dual Stream-Attention
- Performs self-attention and cross-attention within each view
- Iteratively exchanges information between CC and MLO features
- Enhances view consistency and complementary feature learning
4. Multi-View Fusion and Risk Prediction
- Global average pooling applied to each view
- Feature vectors concatenated and passed through a linear layer
- Produces a fused multi-view representation
- Shared cumulative probability layer
- Outputs:
- Multi-view risk prediction
- CC-only risk prediction
- MLO-only risk prediction
🔄 Input / Output
Input
The model expects a batch dictionary with:
current_image_cc: Current CC view[B, 1, H, W]previous_image_cc: Prior CC view[B, 1, H, W]current_image_mlo: Current MLO view[B, 1, H, W]previous_image_mlo: Prior MLO view[B, 1, H, W]time_gap: Time between exams[B, 1]target: Risk labels[B, num_years]y_mask: Valid label mask[B, num_years]
Output
The forward method returns a dictionary containing:
risk_multi: Multi-view fused risk logits[B, num_years]risk_cc: CC-only risk logits[B, num_years]risk_mlo: MLO-only risk logits[B, num_years]
These outputs are consumed by two helper methods:
get_risk_heads(outputs, batch)
Uses the outputs fromforwardto construct(logits, target, mask)tuples for each prediction head:multi: Usesrisk_multiwithtargetandy_maskcc: Usesrisk_ccwithtargetandy_maskmlo: Usesrisk_mlowithtargetandy_mask
This enables multi-head supervision, encouraging both view-specific learning and improved fused predictions.
get_primary_risk_head(outputs)
Uses the outputs fromforwardto return the final prediction for evaluation, defined as:sigmoid(risk_multi)
This represents the model’s primary risk estimate, based on fused multi-view information.
🧩 Integration in This Framework
FlexLMV-Net is implemented as a subclass of BaseRiskModel and:
- Uses the shared data interface
- Supports longitudinal multi-view inputs
- Produces multiple risk heads for multi-task training
- Uses a unified evaluation pipeline via the primary risk head
⚙️ Key Components
- LongitudinalFeatureProcessor: Handles temporal feature alignment using registration
- Feature-Aware Temporal Fusion: Flexibly aggregates longitudinal information from a variable number of prior examinations
- Multi-View Dual Stream-Attention Block: Performs cross-view feature fusion using self-attention and cross-attention
- Continuous Positional Encoding: Injects time-gap information into difference features
- CumulativeProbabilityLayer: Outputs risk over time horizons
- Freezing Mechanism: : Allows pretrained encoder to be frozen during training
📉 Risk Prediction
- Risk is modeled as cumulative probability over time
- Multiple heads allow:
- View-specific supervision
- Improved training stability